Training Day
Running for a few hours certainly gives you plenty of time to think. Earlier this month, more than 55,000 runners shared some hours and more than a few thoughts on a surprise dose of heat and humidity. This was only matched in surprise by the wittiness of this year’s signs. It is hard to imagine the amount of mental energy that wakes up on a random Sunday morning in Chicago.
More and more, many are having a similar wake-up with respect to interacting directly and personally with AI agents. For some time, there has been a looming gap between the media’s representation of personalized AI (see: Her) and the real-life efficacy of agents for personal use cases. Historically, AI and its application accrued first to more ephemeral challenges and then, more recently, to widescale businesses and industries. The public showed up early, and in volume; ChatGPT reached roughly 100 million monthly users in about two months. Yet, when did AI really, really take off as an investment case? Enterprise. Company spending on generative AI went from ~$2B in 2023 to ~$40B in late 2025 with coding as the first widespread use case. Interestingly enough, and for similar reasons, law came next. Something about structured information, rules, and predictable outcomes seems to resonate.
Much of this was a function of the adoption and reinforcement loop. Work, for the most part, comes with grades. Code compiles or it doesn’t, and a brief either survives the partner’s review or judge’s scrutiny. Cursor, for one, learns from which of its code suggestions developers accept and which they reject, and folds the result into the next version. Personal life, however, rarely comes with an explicit grade. At best, there is a momentary reflection and we quickly move on because, well, life beckons.
Who really grades their own Saturday?
Working anywhere near technology will quickly expose the challenges of personalization. Individual use cases are notoriously challenging. Why? Ever tried to write down, step for step, how you make your favorite meal? Even if you were able to, it would likely take you multiple attempts because so much of our procedural mind lies in our subconscious. Most of the time, we are not aware of the subtle preferences that guide our decisions, much in the same way we are not aware of the events which occur on the way to our most frequent destinations. It took a long time for model and workflow development to reach a point where it could handle the uniqueness of completing, well, anything.
Maybe that point has arrived, or is at least close enough to ship. In September, Meta launched Muse, and the list of things it can handle reads like a Saturday to-do list (scheduling conflicts, subscriptions, bills, meal and training plans). Conversely, Instinct skips the app altogether; you text it, or you call it. Personal AI agents, at this stage, exclusively focused on digital errands + tasks in a way that feels undeniably metropolitan. Regardless, if you squint you can see the beginnings of a new arc: unstructured data and unstructured processes building into structure over time. We’ll move beyond the hype of dining reservations and money transfers soon enough.
Now that personal AI is here, at scale, for everyday users, I’ve started wondering: who is training who?
Riding shotgun…with..yourself?
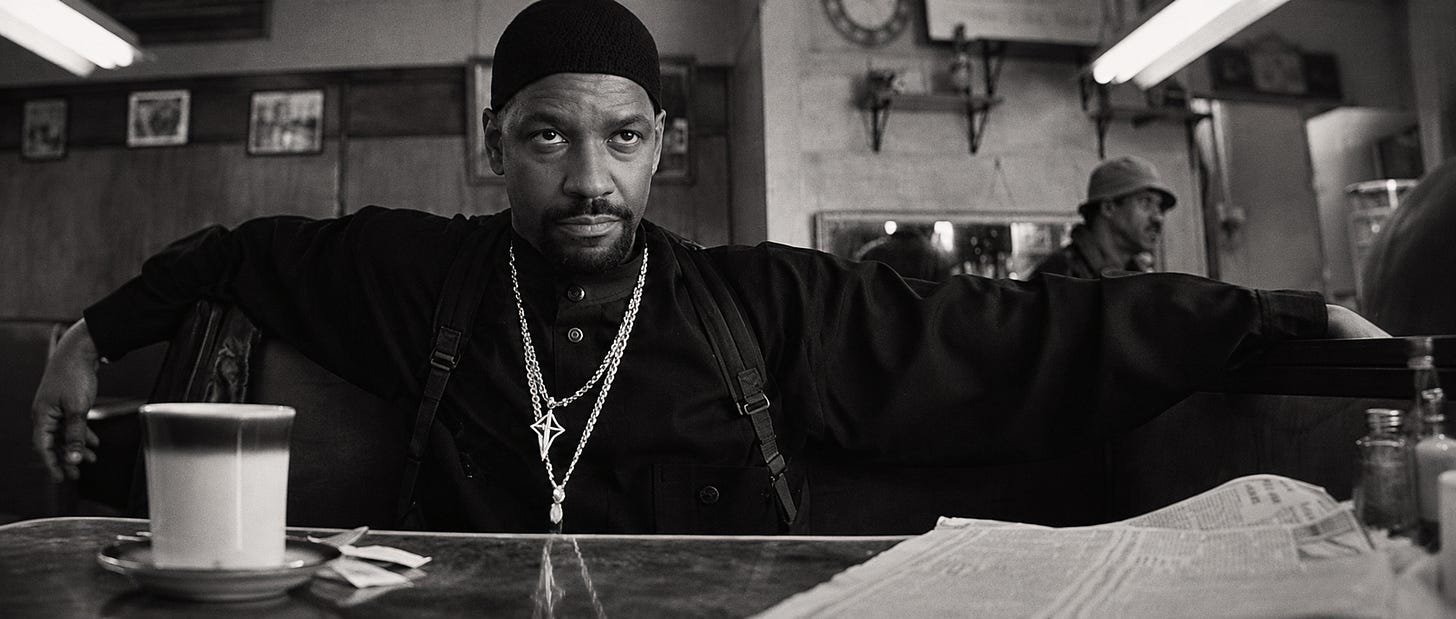
The long arc of AI development, and the surreptitious back and forth that comes with it, reminds me of the movie Training Day. Ethan Hawke plays Jake Hoyt, a wildly idealistic rookie who spends a day in Los Angeles on a ride-along with Alonzo Harris, a veteran LAPD detective, as his evaluation for a narcotics spot. Denzel Washington won Best Actor for his role as an absolute villain (his second, by the way). There’s some irony here, too: David Ayer’s script originally sat untouched for years because it was considered too cynical relative to the corruption ripping through the LAPD in the late 90s. AI, in whatever form, has fought its own share of skepticism through the years.
Ironically, the naivety Ethan Hawke portrays early in the film feels quite a bit like what most of us have felt in 2026 with technology: often feeling around in the closet with the light off. There’s a bit of irony here between how the decisions made early in the training run impact the characters later in the film, often negatively. You can relate if you’ve ever watched your production database evaporate during a turn. In the same way, runners often live their own version of this hellish arrangement: the plan early is never the plan late. There’s a reason why apps struggle mightily with recovery scores and race time predictions. Most of the real world, beyond the screen, is the wild mixture of unstructured data we call living.
The house usually wins, the house always learns
There is a long-standing saying in technology that if there is no price, then you are the product. Does paying your way out solve it? Hardly. Some of Anthropic’s consumer plans train on chats unless the user opts out. Muse users have to opt out to keep their interactions from training Meta’s models. Instinct charges no subscription fee, “for now,” and its terms permit training on user data. In fairness, if you dig into the terms for Thinking Machines, Poolside, and Paper Instruments have similar policies.
Depending on what you value, the trade may well be worth it. The Stanford Digital Economy Lab estimates US consumer surplus from generative AI at $172 billion this year. By that math, the data we hand over is a nominal fee relative to the perceived value. But maybe the value is being created by the user: value accrues in segments to the user, but in aggregate to the provider. Our share shows up one errand at a time and is exercised quickly in the form of a booked table or flight. However - this is the key - whatever the model picked up along the way stays with the provider and, alongside every other user, begins to compound.
Ask a model to show ‘your’ work
My view is that human decision making, preference, and ability to discern nuance is the ultimate objective. However, reinforcement learning will only take us so far in a data and schema environment constrained by documentation and logging. We can only train on what we can structure effectively (shape, repeatability, etc) and grade against. When Ethan Hawke’s character attempts to argue the facts against Denzel’s guidance, he’s met abruptly with:
It’s not what you know, it’s what you can prove.
Models tend to learn in the same way. In fact, asking a personal agent to complete tasks is a great use case for reinforcement learning. Delegation, in other words, attaches a grade to personal life. The table was booked or it wasn’t; the bill came down or it didn’t. Ironically, labs pay real money to build fake websites for their models to practice on. A personal agent works on the real interfaces, with our logins, and guidance at no additional cost to the provider. This seems like an ingenious way to build reinforcement learning at scale: headless execution without needing to run the process. Underneath all the errands, though, is just training data being harvested, effectively, for free. Ironically, the most expensive input for arguably the most important technology of our lifetime is human experience and we are giving it away for free.
Decisions always come alive at Mile 20
With the pace, I’ve started to wonder what happens when AI models begin to run out of training data. David Silver and Richard Sutton first raised this concept last year in The Era of Experience, arguing that human data is seeing some atmospheric pressure and experience will become the main determinant of quality over the long term. Because of venture capital’s close proximity with the edge of emerging trends, it would not surprise you to know that an entire market for data acquisition has grown up in the past two years. Mercor, for one, pays doctors, lawyers, and other specialists to teach models judgment. Other companies like Snorkel and micro1 are attempting to source, funnel, and consume as many business databases as possible. What happens when the entire digital world is effectively mapped into one schema or another? Do models hit a ceiling? Unlikely.
One of the last areas AI will have to conquer is human preference. In the paper The Construction of Preference, Paul Slovic notes that preferences only emerge from inquiry - they are often uncovered in the act of being asked. To be clear, this is markedly different from decisions or processes. For clarity, a decision is what you did and a process is how you did it. A preference is what you wanted, or, more often than we would admit, settled for in the moment. Certainly, a contractor can tell a lab what good looks like for a multitude of tasks across a broad spectrum of industries and applications. But this can’t happen on the time horizon necessary to support the growth targets; only by getting users to consistently provide feedback does AI scale, evolve, and improve to a point of wide acceptance.
As with any technology of importance, there is always some precipice that must be crossed. For personal AI, it seems to have come from an unexpected place: the company at the centerpiece of social media, whose apps over 3.5B people use per day. Especially in the digital world, one of the best mechanisms of understanding preference is to evaluate a person’s social media activity and spending habits. It makes sense that the company with the greatest proximity to consumer technology could have its own agentic workflows since that same company also has the largest training set on human interaction and preferences in the world.
One of the biggest challenges new technologies face in any space, consumer or business, is distribution. The traditional mental models that come to mind are sales teams in B2B and incentives in the consumer space. Increasingly, I think it comes down to attention, but that’s certainly another conversation for another time. The arc tends to run in an order: the supporting technology has to exist, then an interface for use, then, increasingly, connectivity to other tools. In turn, this creates a new surface area for developing or slowing new markets. That’s all the more reason for Amazon and other commerce platforms to either ban competing agentic operators, develop their own players, or partner widely as Shopify continues to champion.
There is always a periphery to knowledge
The arc back to Denzel Washington’s epic performance from AI isn’t all that much of a reach. Payoff is an interesting concept: maybe it is the mob or maybe it is the investors - whichever, the concept of the reveal reductive is as true on screen as it is in real life. Meta (and others) have guided towards $150B in annual capex for the year. Those dollars will have to come from somewhere, and in many cases, much of it will come from users directly or indirectly.
Those costs are easy to model on the balance sheet, but it is fair to ask how much information we are willing to give up in pursuit of the over-optimization of our own lives. Researchers at Rush University in Chicago, of all places, have a name for one version of it, orthosomnia, after patients who chased perfect sleep scores and slept worse. The point of training is adapting. This makes you wonder about the hype of Chicago being a relatively easy marathon: what happens when the humidity and heat begin to bake the race day plan? Personalized AI is supposed to make our lives easier but our lives have an infinite number of variables that have survived codification for centuries.
I am long AI. Yet, I’ve started to wonder: what if the best of what we know about ourselves was never supposed to become training data; rather, what if it’s the very thing that makes it so great to be alive?